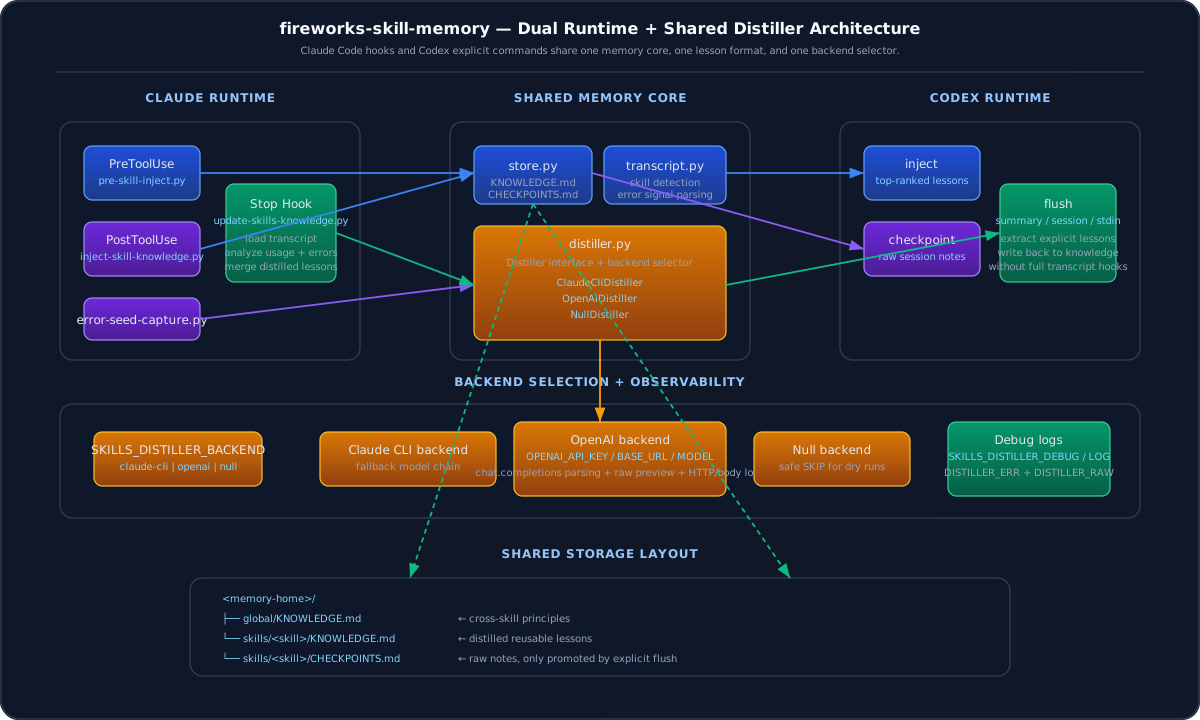
Per-skill experience memory that makes Claude Code and Codex smarter with every session. Session 1 fixes it, Session 2 forgets it, Session 3 redoes it — not anymore. Mistakes get distilled and re-injected before they happen again.
curl -fsSL https://raw.githubusercontent.com/yizhiyanhua-ai/fireworks-skill-memory/main/install.sh | bash
then type /hooks in Claude Code — done
The same API mistakes, broken call sequences, and forgotten proxy configs repeat endlessly because the runtime has no durable memory between sessions. fireworks-skill-memory fixes that — without touching the model.
Each skill gets its own KNOWLEDGE.md; only the relevant skill's lessons are injected, keeping the context window clean. Two layers: global/ + skills/<name>/.
At session Stop (async), Haiku reads the transcript and distills 1–3 new lessons automatically. No manual curation, never blocks you.
PreToolUse fires before a Skill call, so Claude sees past lessons during planning — not after it's already made the mistake.
memory_core/ is shared; claude_runtime.py and codex_runtime.py are thin adapters. Same knowledge, accessible from both.
Never modifies the model, never touches your prompts, never intercepts input. Hooks into exactly two lifecycle points. <5ms injection, pure file I/O.
Pre-loaded KNOWLEDGE.md for 9 official skills (browser-use, voice, find-skills, hookify, superpowers…) — works immediately, no training period.
One curl command, then /hooks in Claude Code. Hooks auto-register.
When Claude reads any SKILL.md, past lessons for that skill inject into context (<5ms). Errors during tool calls get captured to a session seed file.
The async Stop hook reads the transcript, distills 1–3 new lessons, and merges them into the skill's KNOWLEDGE.md (max 100 entries, LRU-style eviction by usage).
The lesson is already there before Claude responds. The loop compounds — every session, smarter than the last.
PostToolUse on Read, Stop async) and does pure file I/O in under 5ms.memory_core/ is shared; Claude Code uses hooks, Codex uses an explicit inject / checkpoint / flush CLI. Same knowledge, both runtimes. Memory defaults to $CODEX_HOME/memories/fireworks-skill-memory/ for Codex.[YYYY-MM] and [HIT:N] (usage counter). Active injection serves the top-20 by HIT count, not the whole file. Eviction prioritizes low-frequency + old entries, capped at 100 per skill.null distiller backend is available if you want zero model calls — manual lessons only.Open source, MIT, built in the open. Sponsorship funds new distillation backends, more pre-loaded skill knowledge, and keeps the loop compounding.